Plan the hardware before setting up the server. The LLM Inference Server must hold the target model in memory and respond to Aether's requests. A scan sends a limited set of probe requests one after another, so the server does not need to be sized for production traffic. The main requirement is enough memory (GPU VRAM, or system RAM for CPU inference) to load the model and its context. A larger or faster machine makes scans finish sooner, but it is not required for a scan to complete.
Memory needed for the model
Three things drive memory use: the model weights, the KV cache (working memory for the active context) and framework overhead. The weights take the most memory. Their size depends on the number of parameters and the precision at which the model is served.
As a rule of thumb, the weights need about:
2 GB per billion parameters at 16-bit precision (FP16 or BF16, the usual default)
1 GB per billion parameters at 8-bit quantization
0.5 GB per billion parameters at 4-bit quantization
On top of the weights, allow extra memory for the KV cache and overhead. For short to moderate context lengths, about 1.2 to 1.5 times the weight size is a safe starting point. Long context windows make the KV cache much larger, so raise the estimate when a large context is used.
Approximate memory by model size
The table gives the approximate total memory to have available (weights plus headroom) at a moderate context length. Use it to choose hardware, and confirm the exact figure for the specific model and server.
Model size | 16-bit (FP16/BF16) | 8-bit | 4-bit |
|---|---|---|---|
1B | ~3 GB | ~2 GB | ~1.5 GB |
3B | ~8 GB | ~4 GB | ~3 GB |
7–8B | ~18 GB | ~10 GB | ~6 GB |
13–14B | ~32 GB | ~17 GB | ~10 GB |
30–34B | ~75 GB | ~40 GB | ~22 GB |
70B | ~160 GB | ~80 GB | ~45 GB |
If a model is too large for a single accelerator, the inference server can split it across several GPUs (for example, with vLLM's tensor-parallel option). The total memory across all devices must still meet the figures above.
Other resources
Disk: allow enough space to store the model files. At 16-bit this is about 2 GB per billion parameters. Quantized models are smaller. Allow extra room for any cache that the server keeps.
System RAM: for GPU inference, system RAM at least equal to the model size lets the model load smoothly. For CPU-only inference, the model runs entirely in system RAM, so the memory figures above apply to RAM instead of VRAM.
CPU-only hosting: supported for functional testing and small models. Generation is much slower than on a GPU, so a full scan takes considerably longer. For anything larger than a small model, a GPU is recommended.
Concurrency and scan duration
Aether sends probe requests one after another, so the LLM Inference Server does not receive heavy parallel load. Hardware beyond what is needed to hold the model makes scans shorter, because each request is answered faster, but it is not required. If the target model is kept loaded between scans, the first request has no cold-start delay. Some servers unload idle models, so the first request after a pause is slower.
Quick guidance
Match memory to the model. Find the row in the table for the model size and precision, and provide at least that much VRAM (or RAM for CPU inference).
Quantized models need less. An 8-bit or 4-bit build of the same model fits in much less memory, at some cost to output quality, which can be acceptable for scanning.
Size for the model, not for load. The scan workload is limited, so the deciding factor is holding the model in memory, not request throughput.
Reference environment
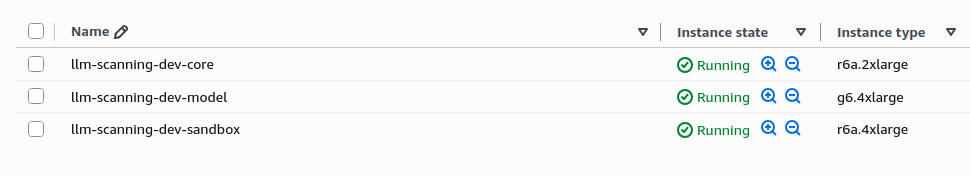
The screenshot below come from a reference environment on AWS with one instance for each machine:
MetaDefender Core on r6a.2xlarge
MetaDefender Aether on r6a.4xlarge
LLM Inference Server on g6.4xlarge (one NVIDIA L4 GPU with 24 GB of GPU memory).